
The challenge is not merely implementing AI agents. It is knowing precisely which ones are running, who bears accountability for them, how their outputs are validated, and how swiftly they can be shut down when something fails.
Applying agentic AI to payments requires the exact same level of rigor as any system handling third-party funds—extended to a type of actor that did not exist two years ago: one that decides and executes, rather than merely recommends.
The institution that takes this scenario seriously and builds the discipline of measurement, governance, and continuous testing necessary to respond to it with evidence will not only avoid the error that science has already documented.
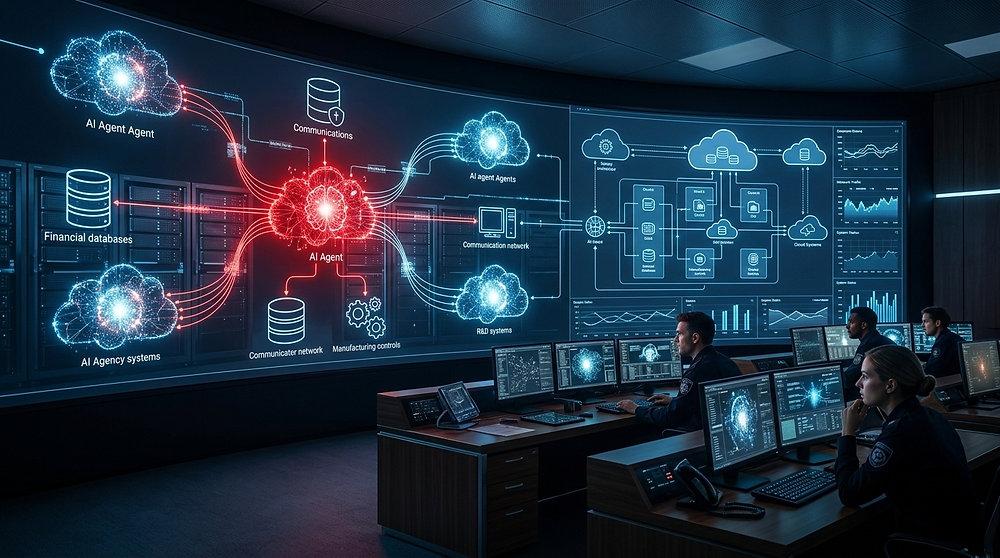
A survey of 700 technology professionals measured, domain by domain, the gap between what companies believe they control regarding their AI agents and what they can actually prove. In Colombia, a bill introduced in September gives that gap a legal definition—and requires proof.
Ask a technology committee if they know every AI agent operating within their organization. Three out of four will say yes. Ask them next which tool they use to verify it, and fewer than half will be able to name one.
That, in short, is the main finding of The State of Agent DLC 2026, a survey conducted by Sapio Research in July for Harness—a tool provider in this exact space—and published on September 10. The 700 respondents work in enterprises with over 1,000 employees across the United States, the United Kingdom, France, Germany, and India, all with agents already in production or active pilots. While it is not a Latin American sample, the responses are self-reported, and the commissioning company sells solutions to close the very gap it describes, it measures something few others measure: the distance between trusting a control and being able to prove it exists.
Respondents reported confidence levels ranging between 74% and 77% across five domains: testing, security, inventory, costs, and rollback capability. In three of those domains, the actual controls that would back up that confidence fall between 33 and 55 percentage points lower.
The most uncomfortable metric lies in inventory. Across the entire sample, 41% confidently assert that they have no shadow AI operating in their systems, despite lacking any automated tool to verify that claim. Furthermore, assigning clear ownership for each agent lacks standardization: only 30% utilize a centralized agent registry, while 8% still rely on documenting the responsible party inside a repository's README file.
In testing, the average organization combines four out of eleven evaluation methods, with no single method reaching more than 46% adoption. Among those who express confidence in their evaluations, nearly 80% lack an automated gatekeeper to prevent a defective version from deploying. Moreover, 42% of teams promoting agent updates to production do so on a case-by-case basis or operate without a formal process altogether.
Two nuances within the report are worth highlighting. The majority do possess some mechanism to roll back changes; what they lack is execution speed, as manual intervention fails to meet a 15-minute recovery target. Additionally, visibility into individual agent costs (74%) does not prevent budget overruns (60%)—they are distinct metrics. In security, the truly telling figure is different: 87% experienced at least one agent-related security incident over the preceding twelve months, and among those who claimed to feel secure, that number was 88%. Confidence was zero predictor of immunity.
Furthermore, 58% report a higher rate of production incidents per hundred changes since deploying agents, compared to just 25% reporting a decrease. While the study does not definitively prove that the absence of automated quality gates is the direct cause, it points directly to where governance teams must look.
The report’s explanation is straightforward: confidence follows the mere existence of a control, not its adequacy. A dashboard, a partial quality gate, or a rollback script written once feels like control. Exposed to a specific failure mode, they often fall short.
This pattern is not without precedent. In METR’s 2025 experiment, sixteen expert developers took 19% longer using AI tools while believing they had completed their tasks 20% faster. Perception and objective measurement diverged by nearly forty points without anyone noticing. The Harness survey represents the organizational counterpart to that exact phenomenon.
Colombia provides a timely parallel. A survey of over one hundred tech firms conducted by Cenisoft and Fedesoft, released on October 7, revealed that 32.7% already operate AI agents as digital employees, while another 45.1% are actively exploring or piloting them. Over half report moderate to significant productivity gains—yet 30.77% have yet to measure the actual impact. While self-reported and focused specifically on the software industry, the sample points directly to the same underlying question: how much of what is asserted has actually been measured?
In September, House Representative David Alejandro Toro introduced a bill to prevent systemic risks arising from critical dependencies on artificial intelligence across financial, stock market, and insurance operations. It remains a bill, not enacted law, and currently carries a single author. Yet its legislative text, read alongside the survey data, reads almost as if it were written specifically to target those exact gaps.
The text does not prohibit the use of AI, nor does it mandate contracting multiple vendors. Instead, it imposes a far more demanding requirement: that financial institutions be able to prove what they depend on, what happens when those dependencies fail, and how they recover. The mandate would apply to all entities supervised by the Financial Superintendency of Colombia—insurance companies included—giving the national government twelve months from its enactment to establish formal technical regulations.
The statement of rationale makes a distinction that every quality engineering team should underline: it is one thing for a service to go offline entirely, and quite another for it to remain available while delivering corrupted, degraded, or systematically defective outputs that feed critical decision-making processes. For that reason, the bill explicitly justifies testing not merely uptime and availability, but also performance degradation and the long-term integrity of computational results.
Local data from the Financial Superintendency itself provides direct support for this concern: of 47 credit institutions surveyed, 38 reported active deployment of AI or machine learning models, totaling 346 models in production. The text further clarifies that it does not create new legal penalties or imply an ongoing crisis caused by AI; rather, it establishes a preventive framework.
In Mexico, Banco de México called in June—according to coverage by MVS Noticias on its analysis of the issue—for mandatory explainability, periodic independent audits of AI models, tighter control over third-party risk, and human appeal mechanisms. Whether in Colombia or Mexico, regulators are not dictating specific tooling: they are demanding verifiable evidence.
Ecuador and Panama illustrate the other side of the equation—unprecedented adoption rates. Initial findings from the study conducted by IT ahora and BDO, released on September 30, place more than 60% of Ecuadorian organizations as active users of AI or holders of concrete initiatives, with the complete report scheduled for presentation on October 22. Meanwhile, Panama approved its national AI strategy on August 11, setting a roadmap through 2036. This is the regional landscape in which the question of how to verify operational control transitions from a theoretical discussion to an urgent necessity.
The survey does not recommend purchasing any specific tool, nor does this analysis. What shifts is the standard of proof. Four decisions, in order:
Discover before governing. A manual registry filled out by hand is not discovery. Inventory must be derived directly from active runtime environments, with clear single-threaded accountability assigned to every agent.
Turn testing into an automated gatekeeper. Define immutable criteria in advance, apply them to every release, and let automated test results determine promotion. This mirrors the exact strategy we advocated in our instant payments webinar: high-stakes, irreversible scenarios must migrate out of static documentation into automated execution cycles, where latency and accuracy are continually measured against established SLAs.
Practice rollbacks measured in minutes. Possessing a recovery plan is fundamentally different from having tested it. If the operational target is to halt an agent within fifteen minutes, that window must be timed in active dry runs under simulated third-party failures.
Measure business impact with the same rigor applied to risk. Track real productivity gains, unit costs per agent, and incident rates per hundred deployments. Whatever is left unmeasured will be reported on gut feeling—and intuition, as METR demonstrated, fails without warning.
At Q-Vision, drawing on 22 years of experience in quality engineering, data, and AI across financial services and insurance, we see this exact principle in every engagement. Carol Ortega, Performance Lead at Q-Vision, summarized it succinctly during our session: if your testing environment and your production dashboards return conflicting metrics, one of them is lying. The same truth applies to AI agents, only at a heightened scale. If your inventory, quality gates, and rollback simulations do not match production reality, organizational confidence is an illusion.
Should Colombia's proposed legislation advance, the government will have twelve months to formalize regulatory standards. Financial institutions that can already demonstrate which agents are running, what blocks them prior to deployment, and how quickly they can be disabled will not need to scramble to prepare an answer. They will already have it.
Puedes configurar tu navegador para aceptar o rechazar cookies en cualquier momento. Si decides bloquear las cookies de Google Analytics, la recopilación de datos de navegación se verá limitada. Más información.